Axis 01 — X · Capability
What can this person deliver now?
Read the range, difficulty and independence already demonstrated in the work.
VITALIS™ S1 · The System
VITALIS™ S1 (VS1) turns work managers already observe into a structured diagnosis of current capability, growth momentum and core vitality.
How it holds together
The system begins by separating three questions that are often collapsed into one impression.
Direct observation, written anchors, dialogue and repeated sampling keep named work instances attached to the reading.
VS1 keeps the three questions separate, supports a proportionate response and returns later to examine what changed.
VS1 is a management process, not a one-off assessment event or a single composite verdict.
01The three readings
An impression“One score says it all.”
One result can hide three different realities.
VS1 keeps X, Y and Z visible as separate readings rather than averaging them into one score.
Axis 01 — X · Capability
Read the range, difficulty and independence already demonstrated in the work.
Axis 02 — Y · Growth momentum
Read the direction and rate at which teaching, imposed change and personal feedback become improved work.
Axis 03 — Z · Core vitality
Read the care, effort and judgement visible when pressure rises, supervision reduces or the task becomes less convenient.
VS1 reads current capability, growth momentum and core vitality separately because each can point to a different management action.
A capable person who is accelerating, a capable person who has stalled and an emerging person who converts feedback quickly should not receive the same response. VS1 therefore keeps X, Y and Z visible as separate readings rather than averaging them into one score.
02Tailored to the work
An impression“A generic competency list will do.”
X is read through work a manager can actually observe in this organisation and this role.
Explanatory examples for Y and Z may be localised without changing their anchors.
The X-axis capability functions, construct boundaries and L1–L5 level logic stay the same. Y and Z retain their meaning and decision logic across industries.
The role language, behavioural examples, observable outputs and realistic role ceiling are written around the industry, organisation and actual work.
A hotel concierge, a retail associate and a bank service officer do not demonstrate reliable delivery in the same way. Select a role to see how the observable details change.
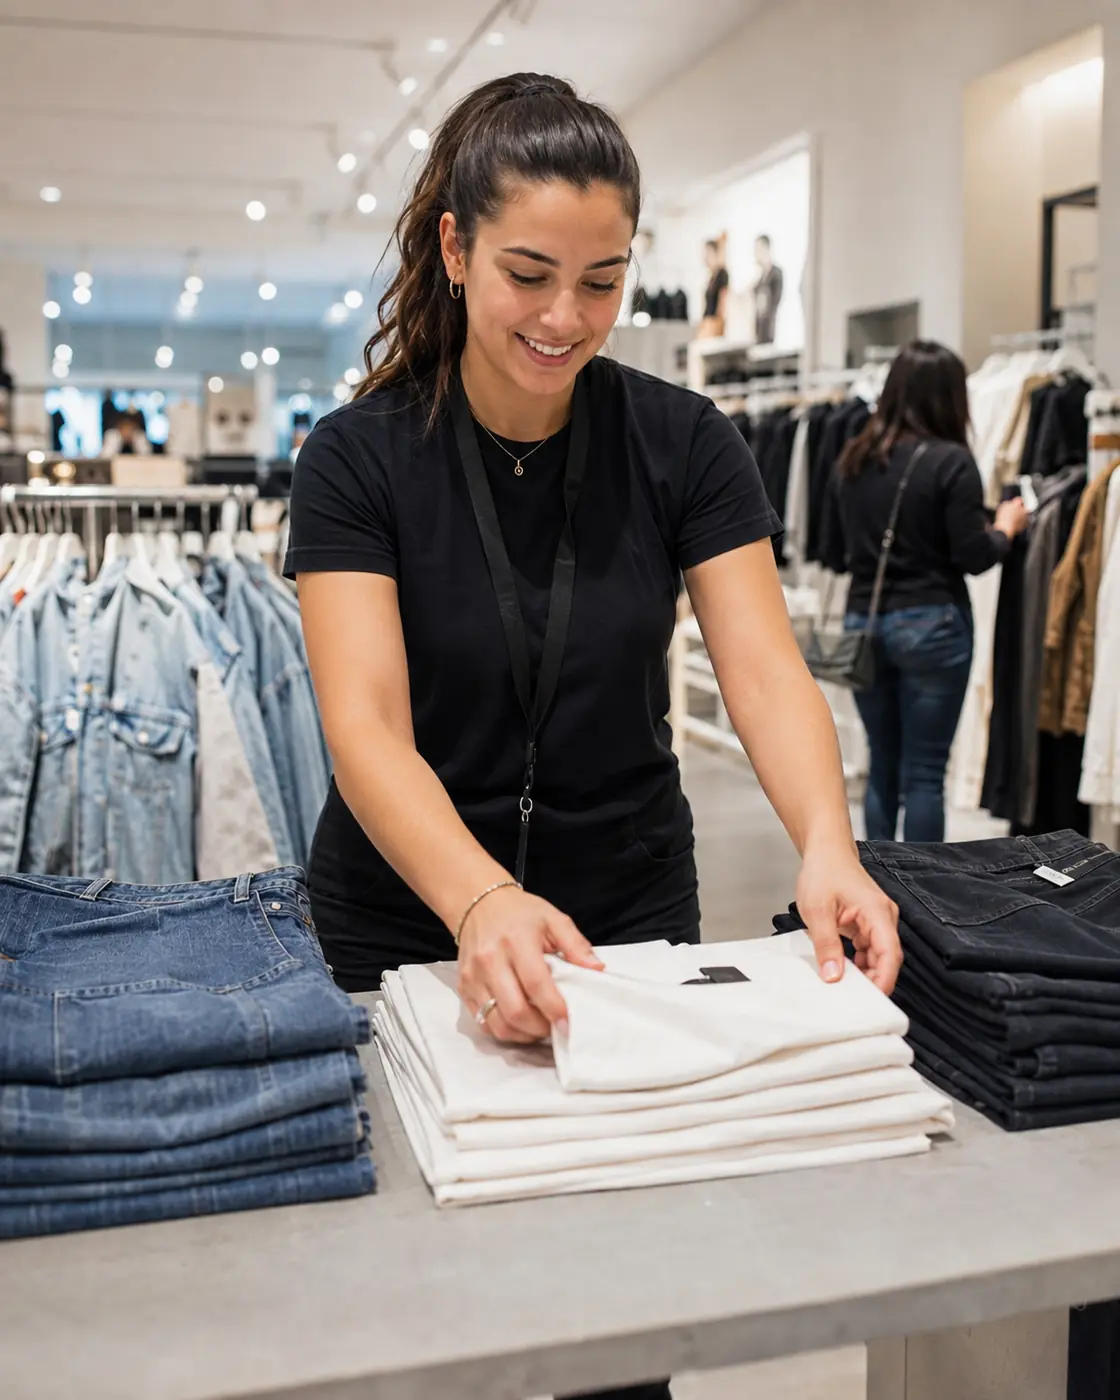
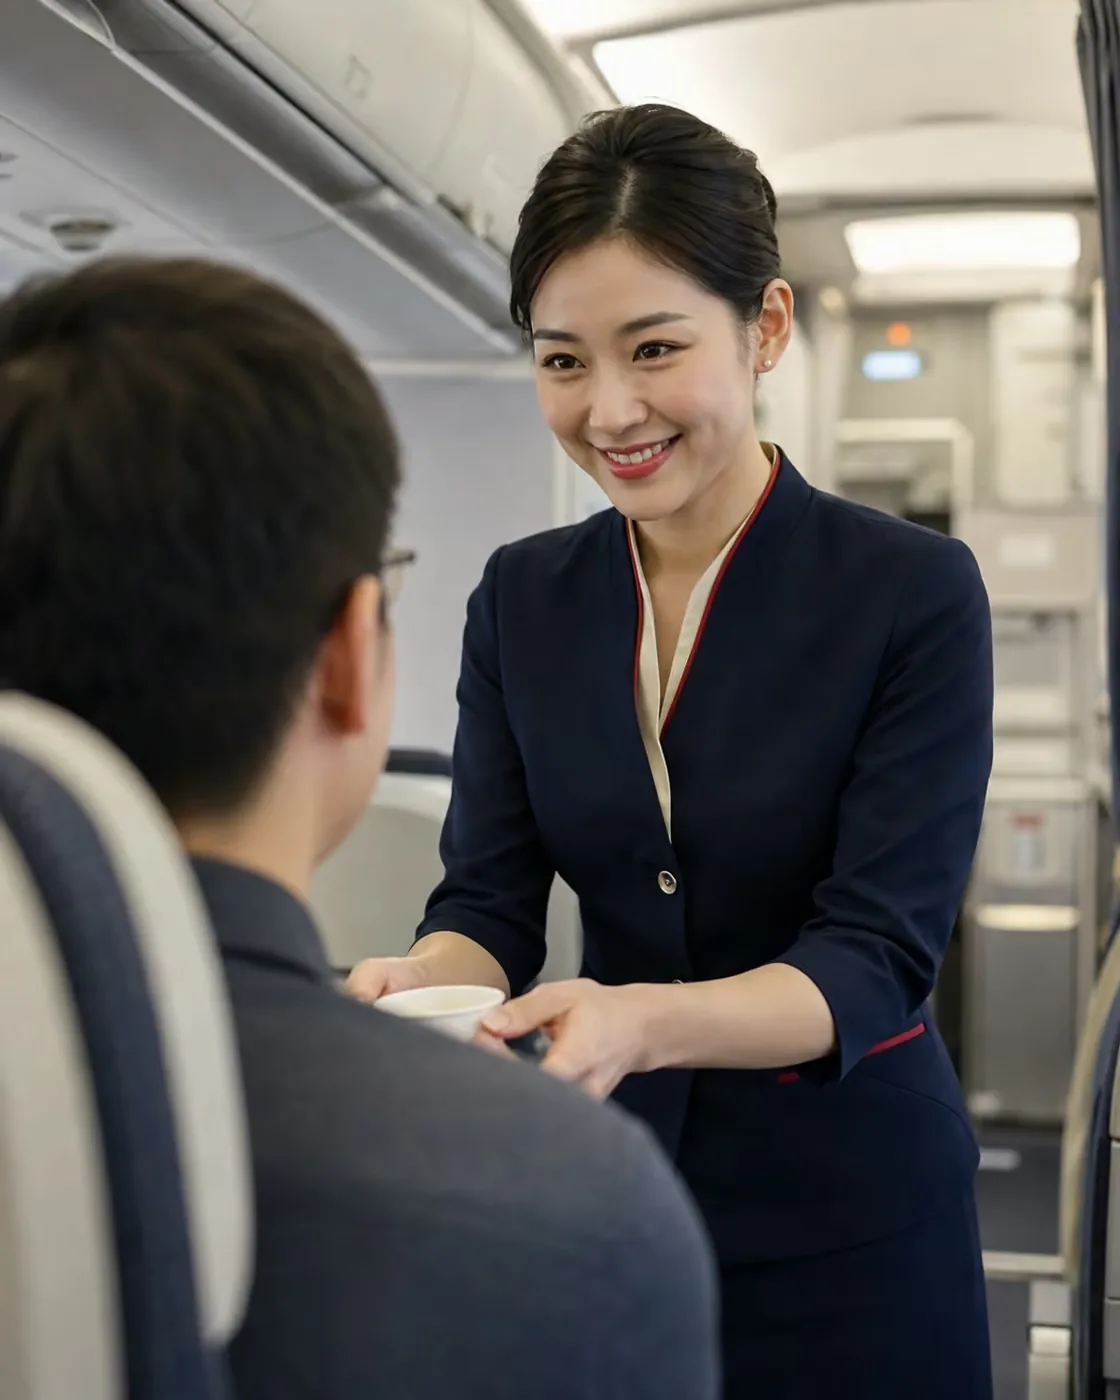
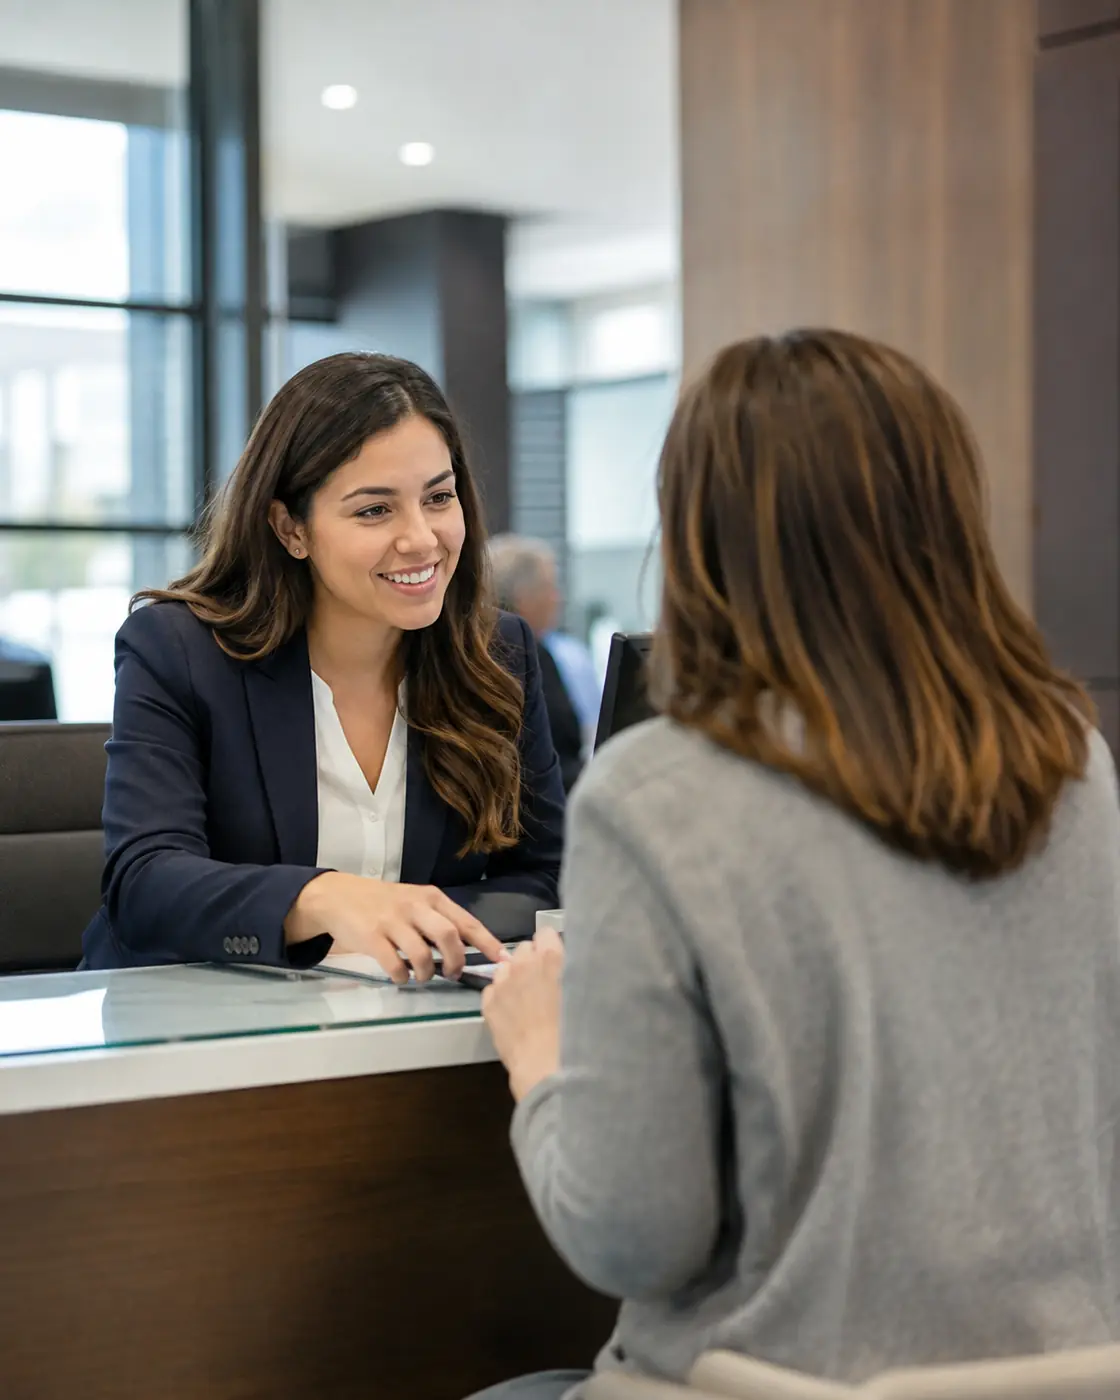
Structure · fixedEvidence · this role
The process starts with role documents, SOPs, output definitions, critical incidents, recurring exceptions and evidence managers can genuinely observe.
Once the questions and evidence anchors are clear, the reading can remain light enough to live inside ordinary management.
03Built into the work
An impression“Another assessment project.”
VS1 is designed to run inside management that is already happening.
The 20–30 minute figure is a current operating target, not a guaranteed burden estimate. Live deployments will examine whether the target, cadence and save-and-resume workflow remain practical in use.
6 returns to 1
Managers log decision-relevant evidence from ordinary work over six to eight weeks. Entries save in parts and resume later.
Input can be spread across short sessions. No separate assessment day or additional work is intended for the purpose of being assessed.
The three readings describe the work. Four deeper analyses extend what can be examined.
04Four deeper analyses
An impression“The score tells you what to do.”
Four deeper analyses help managers examine capability release, current drive, momentum and assignment safeguards.
These four analyses organise evidence that has already been observed. None forecasts a future outcome.
Is capability missing — or is observed capability not being released?
Helps examine whether a constrained result calls for training or a change in conditions.
Reading limit “Potential” means presently observed capability that may not be fully released. It does not calculate future potential or predict intervention uplift.
Does the current pattern of effort, standards and response to change warrant closer review?
Directs attention to current evidence before a concern becomes a general impression.
Reading limit A current review signal, not a prediction of resignation, retention or future performance.
Is the present direction of change moving up or down?
Shows the direction of observed change alongside the current level.
Reading limit Momentum readings, not potential scores or forecasts.
Which observed conditions require a safeguard before important work is entrusted?
Helps keep assignment safeguards proportionate to the observed work.
Reading limit Observed review conditions, not predictions of incidents. Further positive evidence can support a review of the safeguard.
These analyses extend the evidence. They do not turn it into a verdict.
05An evidence boundary
An impression“Written anchors mean they agree.”
Written anchors create the conditions for agreement to be tested — not assumed.
The .43 is a caution, not a target. It is not a pass mark or a VS1 result.
In a 2009 study, 52 internal-medicine faculty rated videotaped encounters. Inter-rater reliability was .43 on the nine-point scale and .40 on the five-point scale; the authors described reliability and accuracy as modest.
It is not a pass mark or a VS1 result. Repeated evidence, explicit anchors, calibration and visible disagreement remain necessary.
Workplace talent diagnosis has no single error-free gold standard. Calibration tests how anchors are interpreted and makes disagreement visible.
Planned live evaluation will examine rater agreement, evidence sufficiency, usability and the 20–30 minute input target.
Evaluation should also examine whether a second reading supports a practical management loop. Method, sample, limits and results should be reported, including if a result is lower than expected.
Diagnostic judgements can be affected by incomplete evidence, observer variation and context.
SOURCE FROM · Cook & Beckman (2009), “Does scale length matter? A comparison of nine- versus five-point rating scales for the mini-CEX,” Advances in Health Sciences Education, 14, 655–664. Participants rated videotaped encounters; some were scripted to represent different competence levels.
Method precedents
VS1 does not claim to invent direct observation, anchored judgement or repeated review; it brings those disciplines together for a specific management problem.
These are design precedents. Their research findings do not validate VS1; VS1 must establish its own evidence.